Lyria 3.5
Text to audio
Lyria 3.5 is Google DeepMind's latest music generation model, and you can generate almost any type of music with it
Find a model. See what it can do.
Browse every available model. Search by name or task.
Text to audio
Lyria 3.5 is Google DeepMind's latest music generation model, and you can generate almost any type of music with it
Text to audio
Lyria 3 is most recent music model from Google
Text to video
Generate a video from a text prompt with Marey, a generative video model trained exclusively on fully licensed data.
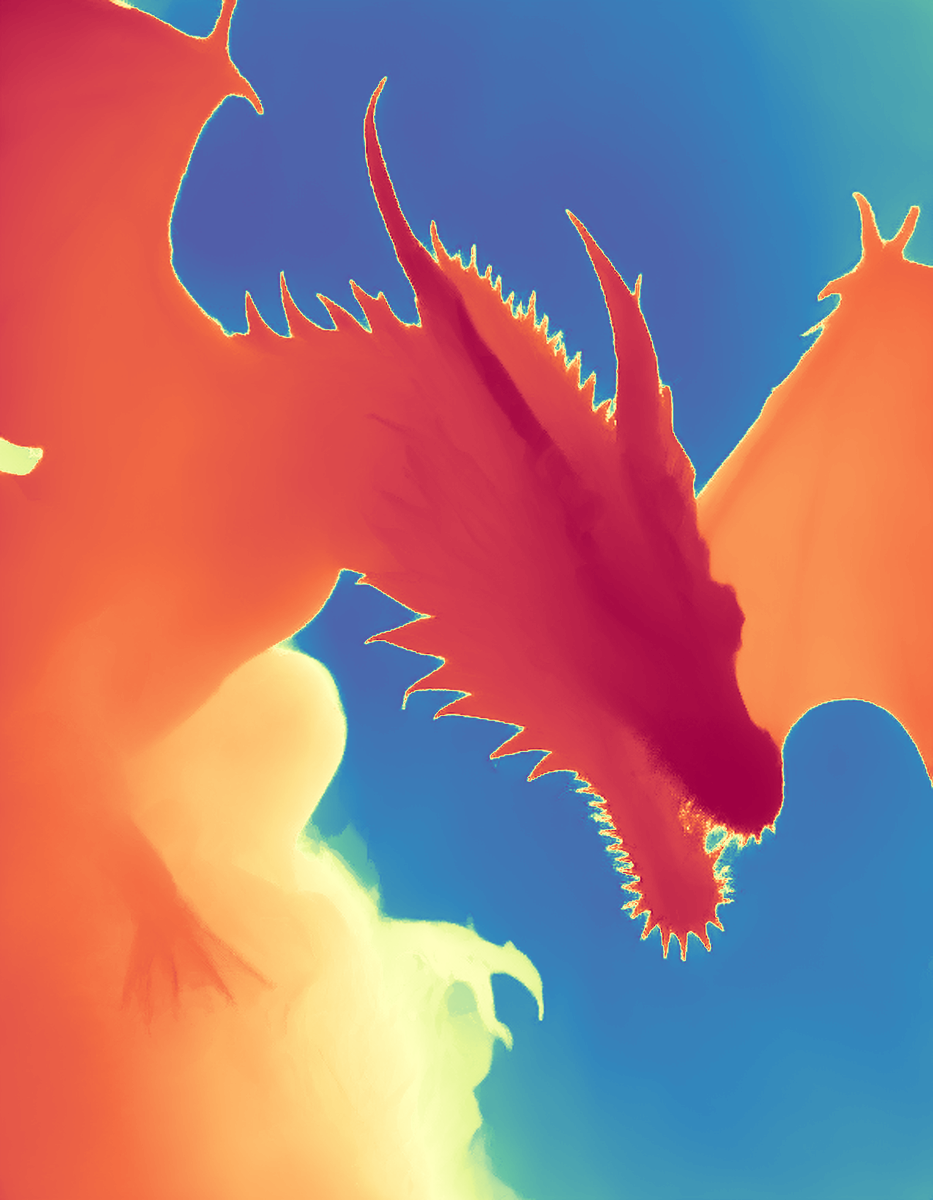
Image editing
Create depth maps using Marigold depth estimation.
Text to image · Image editing
Meta's Muse Image model has faithful instruction-following and exceptional visual fidelity, with fine details like text, plots, and QR codes rendered accurately.
Image editing
Create depth maps using Midas depth estimation.
Text to image · Image editing
Generate high quality images from text prompts using MiniMax Image-01. Longer text prompts will result in better quality images.
Text to video · Image to video · Video editing
H3 Max is a post-trained variant of MiniMax H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
Text to video · Image to video
MiniMax H3 is a frontier video model. This endpoint generates video from a text prompt alone, rendering at 2K in durations from 5 to 15 seconds across seven aspect ratios.
Text to video · Image to video
MiniMax Hailuo-02 Text To Video API (Pro, 1080p): Advanced video generation model with 1080p resolution
Text to video · Image to video
MiniMax Hailuo-02 Text To Video API (Standard, 768p): Advanced video generation model with 768p resolution
Image to video
MiniMax Hailuo-2.3-Fast Image To Video API (Standard, 768p): Advanced fast image-to-video generation model with 768p resolution
Text to video · Image to video
MiniMax Hailuo-2.3 Text To Video API (Pro, 1080p): Advanced text-to-video generation model with 1080p resolution
Text to video · Image to video
MiniMax Hailuo-2.3 Text To Video API (Standard, 768p): Advanced text-to-video generation model with 768p resolution
Text to speech
Generate speech from text prompts and different voices using the MiniMax Speech-2.8 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
Text to speech
Generate speech from text prompts and different voices using the MiniMax Speech-02 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
Text to speech
Clone a voice from a sample audio and generate speech from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality text-to-speech.
Image to video
Create blazing fast and economical videos with MiniMax Hailuo-02 Image To Video API at 512p resolution
Text to audio
MiniMax Music 2.6 creates complete tracks with singing, backing music, and detailed arrangements from lyrics and a style description.
vision
Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.
Image to video
MuseTalk is a real-time high quality audio-driven lip-syncing model. Use MuseTalk to animate a face with your own audio.
Text to image · Image editing
Google's famous original image generation and editing model
Text to image · Image editing
Nano Banana 2 is Google's new state-of-the-art fast image generation and editing model
Text to image · Image editing
Nano banana lite is the efficiency-focused model in the image generation family. Sub-2 second latency with cost-effective generation and editing, fast multi-turn local edits, and 14 supported aspect ratios.
Take it into the studio. See the price before you create.
Browse models here without an account. Sign in when you are ready to create.