Image
Wan v2.2 A14B Text-to-Image A14B with LoRAs
Generate still images with WAN 2.2 A14B and optional LoRA weights.
- Text to image
Sign in to create. Review the credit cost in the studio before running.
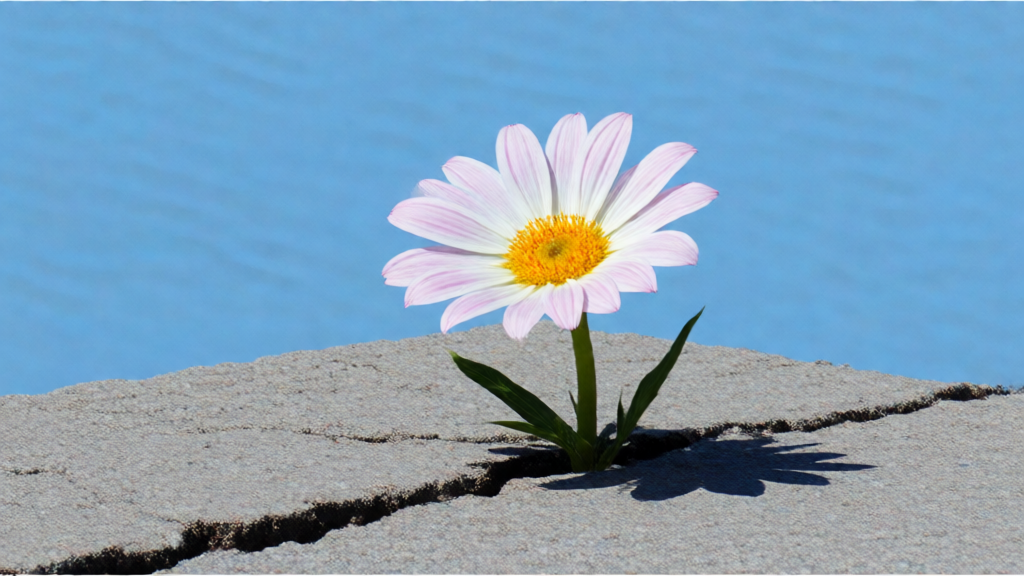
Catalog preview for Wan v2.2 A14B Text-to-Image A14B with LoRAs. Review your own result before publishing.
A starting point.
Generate still images with WAN 2.2 A14B and optional LoRA weights.
Before you publish.
Compare the result with your source, especially object boundaries, fine text, faces and shadows.
Review the quote before running. A failed generation releases its reserved credits. Download the results you want to keep; stored media is retained for 30 days.
Settings and model questionsCheck the available settings and guidance when preparing your input.
Inputs and settings
Set prompt, image_size, negative_prompt and seed. Each LoRA has a path, scale and high/low transformer selection.
Choose regular or no acceleration, guidance settings and 2–40 sampling steps. PNG and JPEG outputs are supported.
Inputs, all modes and APIModel IDs, current input limits and the API generation workflow.
Supported inputs
These fields come from the current studio form for wan/v2.2-a14b/text-to-image/lora. Other modes may require different inputs.
| Input | Type | Requirement | Options and limits |
|---|---|---|---|
prompt | Text | Required | — |
acceleration | Text | Optional | — |
enable_output_safety_checker | On/off | Optional | — |
enable_prompt_expansion | On/off | Optional | — |
enable_safety_checker | On/off | Optional | — |
guidance_scale | Number | Optional | ≥ 1 · ≤ 10 |
guidance_scale_2 | Number | Optional | ≥ 1 · ≤ 10 |
image_format | Text | Optional | — |
loras | List | Optional | — |
negative_prompt | Text | Optional | — |
num_inference_steps | Whole number | Optional | ≥ 2 · ≤ 40 |
reverse_video | On/off | Optional | — |
seed | Whole number | Optional | — |
shift | Number | Optional | ≥ 1 · ≤ 10 |
Check the full model schema for all options and cross-field rules. Request a quote for your selected settings before generating.
Use Wan v2.2 A14B Text-to-Image A14B with LoRAs through the API.
Start with this model ID for the endpoint featured on this page:
wan/v2.2-a14b/text-to-image/lora
Input requirements belong to this model ID. Check a different mode’s schema separately when switching modes.
Check the current model schema for supported inputs and options. Other tasks may use different model IDs.
From quote to result.
Request a credit quote for your input and settings before submitting a generation. A sample output or the price of another model is not a quote for your request.
Follow the generation workflow, then poll the job for its status and result. The API and studio use the same balance.